
Every website owner needs to understand search engine crawl behavior to preserve server resources and protect sensitive directories. A properly configured robots.txt file instructs search bots which sections of your site to fetch and which paths to avoid.
Without clear crawl instructions, search engine spiders consume server bandwidth on administrative folders, internal search queries, and duplicate taxonomy archives. Mastering crawl configuration prevents indexation errors and guides search spiders directly toward high-value content.
Table of Contents
What Is a Robots.txt File and How Does It Function?
A robots.txt file is a plain text file placed in your website root directory that instructs search engine crawlers which pages or folders they can fetch or parse. Understanding what is robots txt ensures webmasters manage crawl access and server resources effectively.
When automated search engine spiders visit your domain, they request the robots.txt file before requesting any html documents or media assets. This initial request represents the first communication handshake between web servers and external search crawlers.

The file operates under the Robots Exclusion Protocol, an established web standard created to coordinate automated crawler activity across domains. It must reside precisely at the root level of your domain hierarchy to function properly.
If your website address is example.com, your crawl directives must live at example.com/robots.txt. Search bots will not search subfolders or nested directories for exclusion guidelines.
Why Is Robots.txt Important for Website Crawl Budget and SEO?
Robots.txt is important because it directs search engine crawl budget toward high-priority canonical pages while conserving bandwidth and preventing server overload. Restricting bot access to staging directories, internal query parameters, and duplicate taxonomy archives preserves organic visibility across key target landing pages.
Search engines assign every domain a finite crawl budget based on server response speed, site popularity, and publishing frequency. When spiders waste crawl budget on admin panels or faceted navigation filters, high-value commercial articles experience indexation delays.
When managing website architecture, webmasters must understand how search spiders crawl newly published URLs. For deeper technical insights into backlink verification and search engine crawl queues, read our complete guide on link indexing methods.
Beyond conserving crawl bandwidth, robots.txt prevents search bots from accessing sensitive staging directories, payment confirmation pages, and internal search result pages. This protection maintains a clean search index composed exclusively of primary landing pages.
Auditing crawler directives requires reliable website diagnostics and technical crawl simulators. Webmasters frequently pair search console data with our reviewed best SEO tools to monitor index status changes.
Understanding Robots.txt Syntax and Crawl Directives
Robots.txt syntax relies on standardized directive key-value pairs defined by the Robots Exclusion Protocol to govern bot behavior. Webmasters declare user agents to isolate specific search spiders, disallow statements to restrict path access, allow rules to permit subfolders, and sitemap locations for rapid discovery.

Directing automated spiders toward canonical URLs prevents indexing delays on fresh articles. To configure sitemap index hierarchies properly for search engines, explore our detailed tutorial on sitemap SEO configuration strategies.
Directives must follow exact case-sensitive formatting, with each instruction written on an independent line. Blank lines separate directive groups targeting different search engine user agents.
Core Robots.txt Directives Explained
Core robots.txt directives comprise user-agent specifications, disallow commands, allow exceptions, sitemap declarations, and optional crawl delays. Each directive instructs search engine crawlers regarding specific file paths, allowing webmasters to isolate administrative directories, unindexed feeds, or private scripts without interfering with public indexing.
The User-agent directive specifies which web crawler the following set of instructions applies to. Using an asterisk applies the subsequent rules universally to all visiting crawlers across the web.
The Disallow directive instructs web crawlers not to access specific directory paths, file formats, or URL query parameters. An empty Disallow line signals to spiders that all website sections remain accessible.
The Allow directive permits search engine bots to access specific subfolders located inside an otherwise disallowed parent directory. This instruction ensures search engines access necessary visual assets.
Disallow vs Allow Directive Precedence
Disallow and allow directives follow strict path length precedence where search engines prioritize the rule matching the most specific character pattern. When conflicting rules match identical URL path lengths, Googlebot gives priority to allow directives, ensuring nested assets remain accessible within restricted parent directories.
Search engines evaluate conflicting directives by measuring character string length rather than line position order in your file. More specific path rules always override general directory rules.
For instance, an allow rule for /wp-content/uploads/ contains more characters than a disallow rule for /wp-content/. Googlebot executes the more specific allow directive without parsing conflict errors.
How to Create Robots.txt File for Your Website
Learning how to create robots txt requires generating a plain text file containing precise user-agent and disallow directives before placing it in the server public root directory. Webmasters can produce this document using local text editors, web hosting control panels, or specialized WordPress SEO plugins.
Website administrators can generate robots.txt through manual file creation or dynamic plugin generation. Both methods achieve identical crawler management goals when formatted according to web standards.
Broken internal hyperlinks waste valuable crawler bandwidth across your domain. To detect and resolve 404 response errors across your database, review our tutorial on how to fix broken links in WordPress.
How to Create Robots.txt via Text Editor and FTP or cPanel
Creating robots.txt manually involves writing directives in Notepad or TextEdit, saving the file with lowercase utf-8 formatting, and uploading it to public_html via SFTP or cPanel File Manager. Testing root access through your browser ensures search bots read server directives accurately upon arrival.
Open a basic text editor such as Notepad on Windows or TextEdit on macOS. Never use word processing software like Microsoft Word because rich text formatting injects hidden characters.
Input your target directives, specifying your intended user agents, disallow paths, allow paths, and absolute XML sitemap location. Save the document with the exact lowercase filename robots.txt.
Connect to your web hosting server through SFTP or log in to your hosting cPanel dashboard. Navigate to your root directory, commonly named public_html or htdocs, and upload the file.
How to Create Robots.txt WordPress Configuration Using Rank Math
To create robots txt wordpress site administrators can use Rank Math SEO to edit virtual robots directives directly from the administrative dashboard. Navigating to General Settings and selecting Robots.txt allows instant updates without modifying physical server files or navigating complex web hosting control panel directories.
WordPress automatically creates a dynamic virtual robots.txt file if no physical file exists in your server root directory. Rank Math provides an integrated visual editor to modify these virtual directives.
Log in to your WordPress dashboard, navigate to Rank Math SEO, and select General Settings. Click on the Robots.txt tab from the left sidebar navigation menu.
Enter your customized crawl rules into the text editor window. Rank Math automatically verifies syntax integrity and saves updates directly into your virtual server response header.
Optimal Robots.txt File Template for WordPress Sites
An optimal WordPress robots.txt template disallows administrative screens while permitting full search crawler access to public assets like CSS, JavaScript, and media uploads. Modern search engines require unrestricted rendering access to evaluate mobile responsiveness, visual layout shifts, and critical on-page ranking factors accurately.
Legacy WordPress tutorials frequently recommended blocking /wp-includes/ and /wp-content/ directories entirely. This outdated practice prevents search engines from loading stylesheets and scripts, causing mobile rendering errors.
The standard, verified robots.txt template for modern WordPress installations is displayed below.
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Disallow: /trackback/
Disallow: /xmlrpc.php
Disallow: /feed/
Disallow: /go/

Sitemap: https://yourdomain.com/sitemap_index.xml
This clean configuration blocks administrative functions and outgoing affiliate redirect links while allowing search engine bots complete access to theme assets and media uploads.
How to Test and Validate Your Robots.txt File
Testing and validating your robots.txt file confirms that search spiders can access public URLs while honoring disallow restrictions on private folders. Webmasters utilize web browsers, HTTP header response inspectors, and automated crawling tools to verify directive syntax before deploying major structural website modifications.
After uploading your file, verify live accessibility by opening a web browser in incognito mode. Enter your domain URL followed by /robots.txt to review the active text output.
If your browser returns a 404 error or redirects to your homepage, check file permissions on your server. Web servers require 644 file permissions for robots.txt to respond correctly.
How to Test Robots.txt Using Google Search Console
Google Search Console provides a dedicated Robots.txt Report that shows the exact version fetched by Googlebot, highlighting parsing warnings and blocked URL counts. Webmasters enter live URLs into the testing field to verify whether specific crawl directives successfully permit or restrict Googlebot indexing.
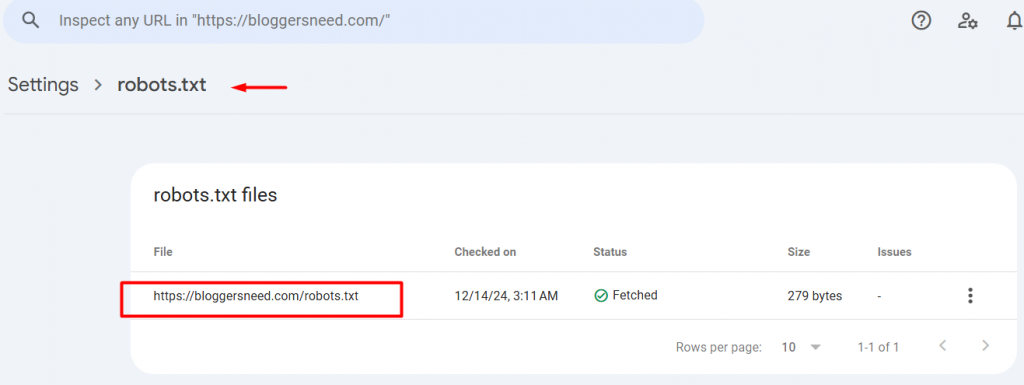
Google Search Console maintains an updated Robots.txt Report under the Settings menu in your property dashboard. This report displays your current live file version and timestamps recent crawler fetch requests.
The report highlights syntax warnings, line errors, and unsupported directives encountered during automated Googlebot passes. Reviewing this screen alerts webmasters to unintentional blocking issues before search rankings drop.
Robots.txt Best Practices for Maximum Crawl Efficiency
Following robots txt best practices ensures search engine spiders navigate your web hierarchy without wasting crawl budget on duplicate or low-value pages. Essential protocols include using exact lowercase file naming, avoiding relative path ambiguities, validating UTF-8 character encoding, and maintaining unblocked access to critical scripts.
Implementing disciplined configuration standards prevents unexpected indexation drops and crawl bottlenecks. Adhering to technical protocols guarantees search engines interpret your directives without parsing ambiguity.
Essential Robots.txt Best Practices for Clean Crawling
Clean crawl architecture requires placing robots.txt strictly in the root domain, declaring absolute sitemap URLs, and keeping disallow rules concise and non-redundant. Regular audits ensure outdated promotional subdirectories or migrated taxonomy paths do not linger in server directives, preventing unnecessary crawler confusion.
Always name your file robots.txt in all lowercase letters. Web servers are case sensitive, meaning filenames like Robots.txt or ROBOTS.TXT will generate 404 response codes.
Define one directive per line without combining commands. Use forward slashes at the start of all path parameters to establish absolute relative directory structures.
Do not use robots.txt to hide sensitive user records, private payment data, or confidential server files. Anyone can read your robots.txt file by navigating to the public URL.
Critical Pitfalls and Mistakes to Avoid in Robots.txt
Common robots.txt mistakes include blocking CSS and JavaScript stylesheets, attempting to deindex private pages with disallow directives, and leaving blanket disallow commands active after staging migrations. These configuration errors degrade Googlebot page rendering, harm mobile usability scores, and prevent removal of sensitive URLs.
The most catastrophic error in website management is leaving Disallow: / active on live production domains. Development teams often use this rule on staging environments but forget to remove it during launch.
Another frequent mistake is attempting to remove indexed pages from search results using disallow directives. If Googlebot cannot crawl a page, it cannot view the noindex meta tag.
To deindex existing URLs, allow crawling in robots.txt while applying a noindex meta robots tag in HTML headers. Spiders will crawl the page, process the tag, and drop the URL from SERPs.
Advanced Robots.txt Techniques for Modern Publishing
Advanced robots.txt configurations provide granular traffic regulation by segmenting permissions across commercial search engines, commercial AI data miners, and automated scraping spiders. Implementing specialized user-agent blocks protects proprietary website content and bandwidth while maintaining complete indexing access for major organic search discovery engines.
As web crawling technologies expand, publishers face increased server overhead from non-search scrapers and commercial data aggregators. Advanced directive grouping allows selective crawler permissions without compromising search rankings.
Managing AI Bots and Automated Scrapers
Managing AI web scrapers requires defining dedicated user-agent blocks for specific bots like GPTBot, CCBot, and ClaudeBot within your robots.txt file. This prevents generative artificial intelligence models from scraping your publishing archives for training datasets without interrupting organic search crawling from Googlebot or Bingbot.
Publishers can restrict artificial intelligence scrapers while preserving search engine visibility. Directives targeting OpenAI, Anthropic, and Common Crawl bots are formatted as shown below.
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: CCBot
Disallow: /
These specific blocks safeguard your original editorial writing from unauthorized data harvesting. Googlebot and Bingbot continue indexing your articles normally without interruption.
Integrating XML Sitemaps for Rapid URL Discovery
Adding sitemap directives to robots.txt instructs web crawlers where to locate your XML sitemap index during root crawl passes. This declaration ensures automated spiders discover newly published posts, modified taxonomies, and media assets without relying solely on internal link crawl depth.
Always specify the absolute canonical URL when declaring your sitemap directive. For example, use Sitemap: https://example.com/sitemap_index.xml rather than relative path shortcuts.
If your website operates multiple dedicated sitemaps for articles, ecommerce products, and image assets, list each sitemap index URL on a separate line at the end of the file.
Frequently Asked Questions About Robots.txt
Frequently asked questions regarding robots.txt configuration, syntax rules, and WordPress SEO implementation address crawl budget allocation, directive conflicts, and search engine bot behavior. Understanding these distinctions prevents indexing errors, protects administrative directories, and optimizes organic search visibility across desktop and mobile devices.
Is Robots.txt The Same As Noindex?
Robots.txt is not the same as a noindex meta directive because robots.txt restricts crawler access while noindex allows crawling but prevents search display. Blocking a page in robots.txt stops spiders from reading on-page tags, causing URLs with external links to index as bare snippets.
Robots.txt restricts crawl access to specified folders, while the noindex meta tag instructs search engines not to display a page in organic results. To deindex a page permanently, leave it crawlable in robots.txt and apply noindex.
Can Search Engines Ignore Robots.txt Files?
Major search engines like Google and Bing honor valid robots.txt directives, but malicious bots, scrapers, and certain archive crawlers routinely ignore exclusion rules. Because robots.txt operates as an advisory protocol rather than an access firewall, sensitive data must be insulated behind server-level HTTP authentication.
Search engines like Google and Bing consistently follow robots.txt directives. Rogue bots, scrapers, and malicious spambots may ignore crawl rules, making server firewalls and password authentication necessary for private files.
Can Robots.txt Prevent Duplicate Content Issues?
Robots.txt cannot resolve duplicate content issues because disallowing a URL prevents search bots from viewing canonical tags, page content, or redirect headers. When identical or parameterized pages are disallowed, search algorithms cannot consolidate ranking signals, requiring canonical link tags or server 301 redirects instead.
Robots.txt restricts crawling but cannot consolidate duplicate content signals. If search spiders cannot crawl duplicate pages, they cannot read rel=canonical tags, making canonical declarations or 301 redirects the proper technical solution.
Can Robots.txt Be Used To Block Specific Crawlers?
Robots.txt allows webmasters to block specific crawlers by declaring individual user-agent directives paired with disallow rules. Site operators can permit primary search engine spiders like Googlebot while restricting aggressive automated scrapers, third-party SEO analysis crawlers, and AI training bots from consuming server resources.
Site owners can restrict specific crawlers by specifying their declared User-agent name followed by a Disallow: / directive. This technique blocks specific third-party tools while leaving organic search engine access intact.
Can Robots.txt Prevent Or Control Link Indexing?
Robots.txt cannot prevent or control link indexing because disallow rules only govern crawler access, not whether external hyperlinks appear in search indices. When external websites link to a disallowed URL, search engines index the destination address using anchor text signals without fetching page content.
Robots.txt directs crawl paths rather than indexation equity. If other web pages link to a blocked URL, search engines may still index the address as an empty snippet without fetching on-page copy.
Why Should You Insert a Sitemap URL in Robots.txt?
Inserting a sitemap URL in robots.txt provides search crawlers with an immediate path to your XML sitemap index during root crawl passes. This declaration ensures automated spiders discover newly published posts, modified taxonomies, and media assets without relying solely on internal link crawl depth.
Declaring your XML sitemap in robots.txt allows web crawlers to locate your complete content architecture automatically. This helps search engines discover new articles faster and prioritize critical pages during crawling.
I’m Abdullah Prem, a passionate blogger with over 10 years of experience. I created BloggersNeed to produce high-quality, easy-to-understand articles, guides, and tutorials that help people start their blogging journey. Specializing in WordPress, Hosting, Themes, and online money-making strategies, I’ve been featured on leading tech platforms such as Tech.co, Cloudways, Business2Community, Leadpages, GoodFirms, and ShareThis. BloggersNeed.com